

From
StayCurrentMD
Comment on: Using Artificial Intelligence to Label Free-Text Operative and Ultrasound Reports for Grading Pediatric Appendicitis
jpedsurg.org shows its articles on its own site.
Read the article on jpedsurg.org ↗Article · Apr 2024 · 1 min read
In brief
In brief
This commentary discusses a study demonstrating ChatGPT-4's superior performance over manual methods in extracting and grading pediatric appendicitis severity from operative and ultrasound reports. The AI system achieved higher precision and lower error rates, highlighting potential applications of large language models in automated clinical documentation analysis.
- ChatGPT-4 outperformed manual extraction in labeling pediatric appendicitis reports with higher precision and F-score.
- AI chatbot demonstrated significantly lower error rates than humans when assigning appendicitis severity grades.
- Natural language processing can automate clinical data extraction from free-text operative and ultrasound reports.
- AI tools may improve consistency and efficiency in retrospective chart review for pediatric surgical research.
Written by the GCMD Library team from the article.
I have read with great interest the manuscript titled “Using Artificial Intelligence to Label Free-Text Operative and Ultrasound Reports for Grading Pediatric Appendicitis” by Abu-Ashour et al. [1]. The authors showcase the superior performance of ChatGPT-4 compared to manual data extraction, achieving higher precision and an F-score that strikes a balance between accuracy and comprehensiveness. Importantly, the Artificial Intelligence (AI) chatbot demonstrated a significantly lower error rate than humans when assigning the appendicitis grade.
Educational content from recorded physician discussions — not medical advice. Talk to your (or your child's) care team about your situation.
Video
Intestinal Atresia Types Explained: Grossfeld Classification for Pediatric Surgery
1 min · Published Sep 2026
Video
Derivation and validation of the Pediatric Community-Acquired Pneumonia Severity (PedCAPS) score: A prospective cohort study
50 s · Published Sep 2026
Video
FETO for Late-Diagnosed Severe Congenital Diaphragmatic Hernia (CDH) at Cincinnati Children's with Dr. Beth Rymeski
4 min · Published Sep 2026
Video
Severe Congenital Diaphragmatic Hernia (CDH) Case: FETO Management & Unexpected Findings with Dr. Beth Rymeski
3 min · Published Sep 2026
Video
Fetoscopic Endoluminal Tracheal Occlusion (FETO) Procedure: Step-by-Step Guide with Dr. Beth Rymeski
4 min · Published Sep 2026
Video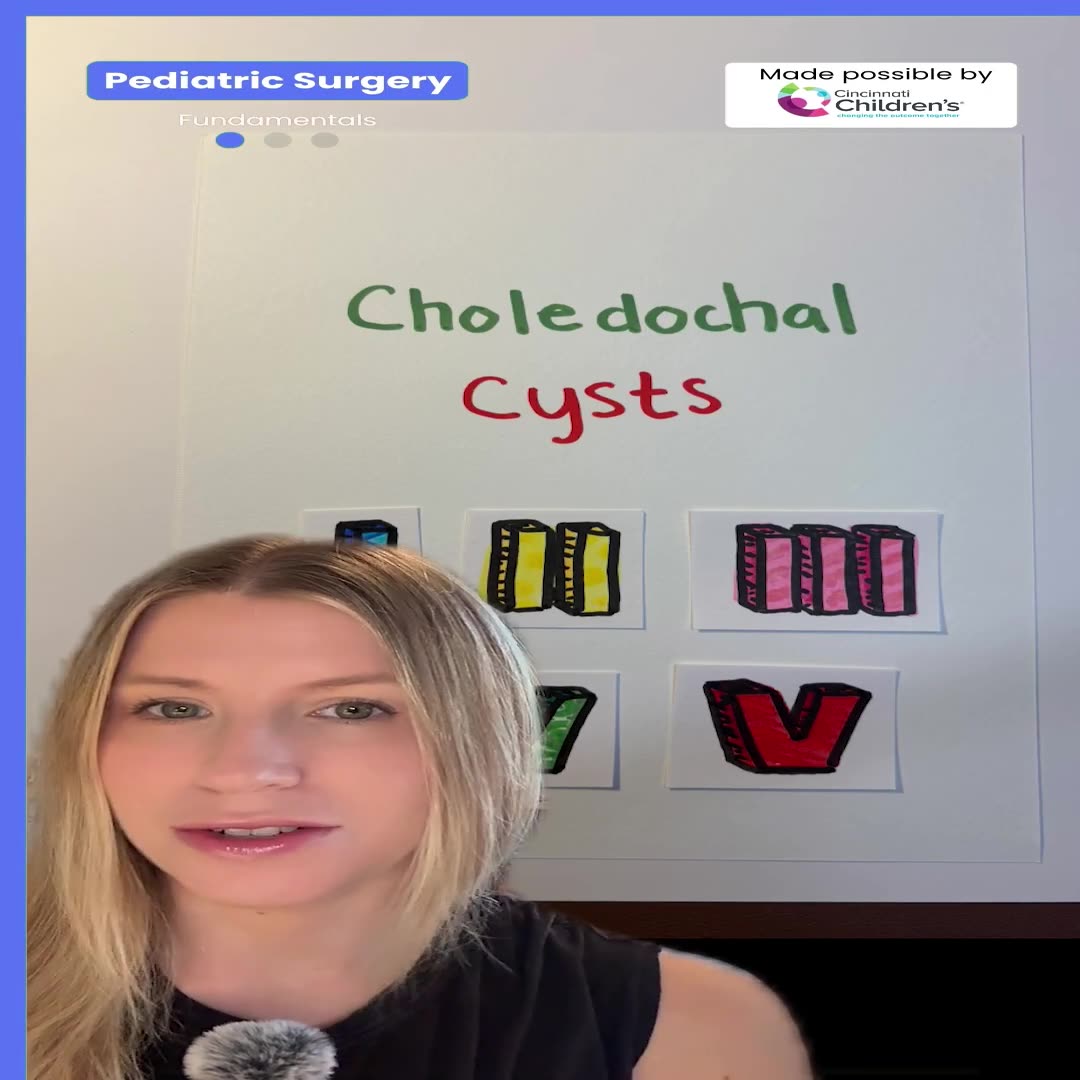
Choledochal Cyst Types Explained: Pediatric Surgery Fundamentals
1 min · Published Sep 2026